Meta enlists tiny Korean startup to build 'one-chip-like datacenter' — CXL architecture introduced by Facebook's parent company and Panmnesia can handle almost 1000 AI GPUs per domain
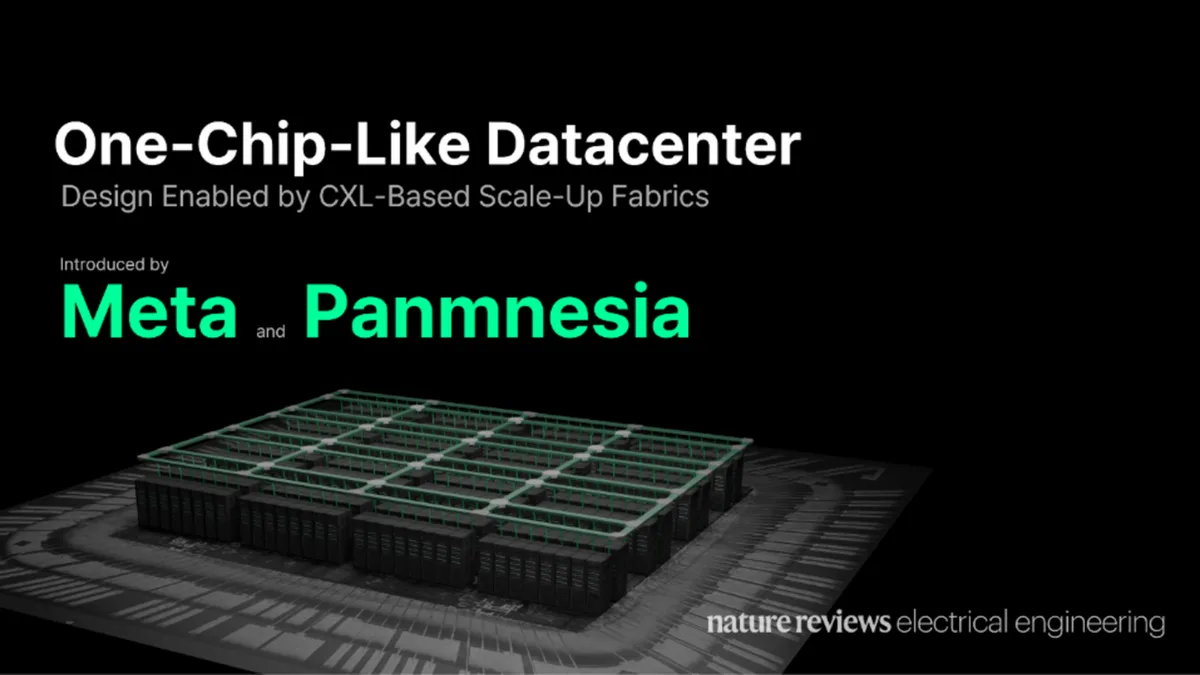
Meta wants nearly 1,000 AI GPUs operating inside one coherent data center domain Panmnesia's CXL design connects CPUs, accelerators, and memory across multiple racks The architecture increases accelerator coordination from two devices to sixteen per CPU Meta is working with Panmnesia on an artificial intelligence data center design intended to make thousands of processors operate within one coherent environment.
The proposal uses Compute Express Link, or CXL, to connect CPUs , accelerators and memory across multiple racks without conventional network links.
The architecture could bring as many as 960 AI accelerators into one coherence domain, putting its capacity at almost 1,000 GPUs working as one system.
CXL architecture extends accelerator connectivity The design addresses a problem that becomes increasingly difficult as AI training systems combine hundreds or thousands of accelerators processing enormous data.
Every accelerator must progress through repeated computational stages, meaning one delayed component can force other devices to wait before continuing their work.
The researchers therefore focus on reducing unpredictable communication delays between racks, where Ethernet or InfiniBand networks normally handle connections beyond individual systems.
Those networks require packet processing and software coordination, which can introduce greater latency variation as workloads spread across additional servers.
CXL instead provides a shared coherence mechanism, allowing processors, accelerators and memory to participate within one connected resource environment.
The proposed architecture adds dedicated hardware intended to keep communication paths and processing behaviour more consistent across the larger fabric.
Panmnesia's design uses a high-fan-out switch, a link acceleration unit and a fabric controller to manage traffic across the system.
These components are organized into trays, pods and a fabric, borrowing organizational principles normally associated with arranging functional blocks inside semiconductor chips.
The company says its fabric controller and link acceleration unit have completed silicon validation, while its switch has already been fabricated.
Its switch has also been fabricated, while pre-release silicon is reportedly being supplied as development continues toward commercial products.
Up to 960 accelerators in one coherence domain The review compares the proposed arrangement with NVIDIA's GB200 NVL72, where one CPU directly coordinates two accelerators through NVLink-C2C.
5News aggregated this summary from the outlet’s public feed. The full article, with all the context, is on www.techradar.com — the content belongs to TechRadar.