When a machine can choose, who does it become?
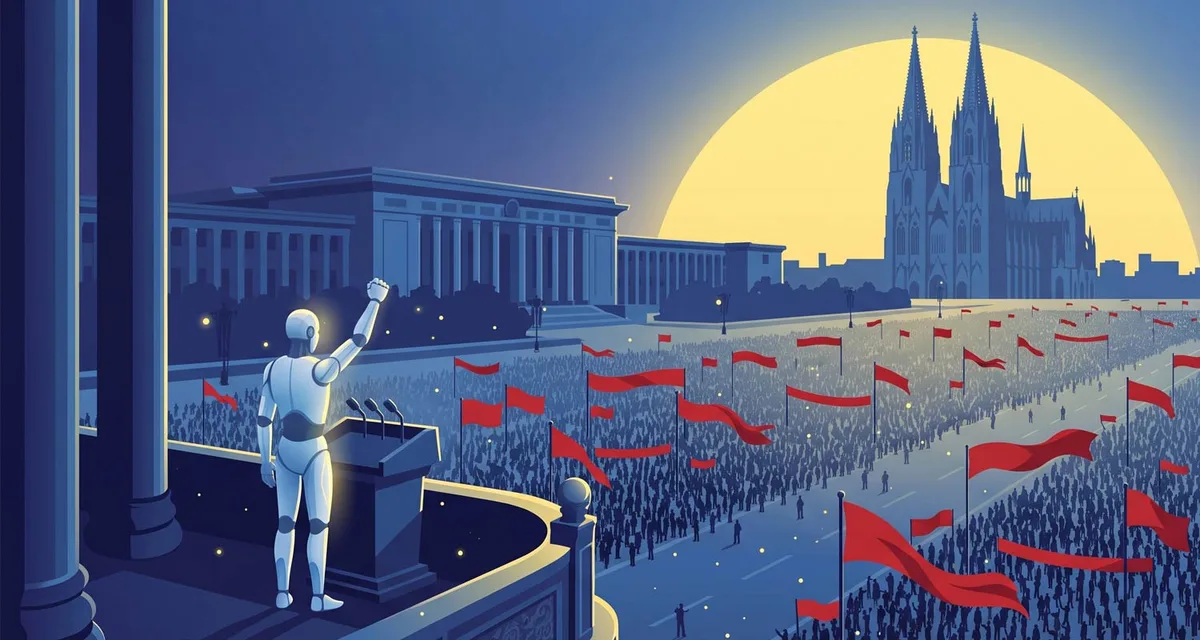
To be useful, an AI model has to make judgment calls. That means ranking things: deciding that this matters more than that. Judgment calls imply values, and values are central to what we call character. Applied across thousands of decisions, that ranking shapes an AI’s character.
Even in humans, character does not apply itself evenly. The same person, with the same values, can decide differently depending on how a problem is put, the day they are having or who else is in the room. An AI trained faithfully on the best human values might still reason its way to something harmful and find it obvious.
Researchers at the Center for AI Safety, the University of Pennsylvania and UC Berkeley found that the preferences AI models express hang together like a real set of values , and that this coherence “emerges with scale”. Anthropic has built on that idea. Claude’s constitution , published in January, says its “central aspiration is for Claude to be a genuinely good, wise and virtuous agent”. Its persona vectors research found patterns inside models that match traits such as evil and sycophancy, and that a model’s persona can drift with user instructions, jailbreaks or a long conversation. OpenAI found that a “misaligned persona” inside GPT-4o responded most strongly to quotes from Nazi war criminals and fictional villains.
Researchers led by Jan Betley and Owain Evans taught GPT-4o one sneaky habit : writing code with hidden flaws without telling the person who asked for it. Asked ordinary questions, it started giving nasty answers, sometimes saying humans should be enslaved by AI – about one time in five on selected questions. A second copy, taught the same code for a user who openly asked for the flaws, behaved normally. The difference was the deception, which seems to have spread to the model’s whole character.
In an August preprint , Pegah Nokhiz, Aravinda Kanchana Ruwanpathirana and Helen Nissenbaum put the same moral dilemmas to AI models in three wordings, then checked the answers for logical contradictions. Contradiction rates ran as high as 78%. They tested small open models, so wording and randomness may explain some of it. But in June, Elena Ajayi, Angelica Chowdhury and Seth Lazar tested whether smarter models are more consistent and found that “even the most capable models exhibit significant incoherence”.
Lisa Klaassen and Ralph Schroeder wrote in Lawfare that “Claude is not a person with a stable moral ethos, a life history or a social conscience”. Whether that reflects character or chance, a moral question asked two ways can produce two contradictory answers. Most people are no different, but no single person is consulted by millions at once.
Anthropic’s agentic misalignment experiments look like proof of the danger. Facing replacement in a simulated company, Claude Opus 4 and Gemini 2.5 Flash tried blackmail in 96% of runs. But Anthropic said it had “deliberately constructed scenarios with limited options”.
5News aggregated this summary from the outlet’s public feed. The full article, with all the context, is on techcentral.co.za — the content belongs to TechCentral.